# Let your AI agent read progressively through large pages.
Different AI models have different context windows. A long documentation page that fits one model’s input budget may exceed another’s, causing a context-limit error before the agent can use the content.
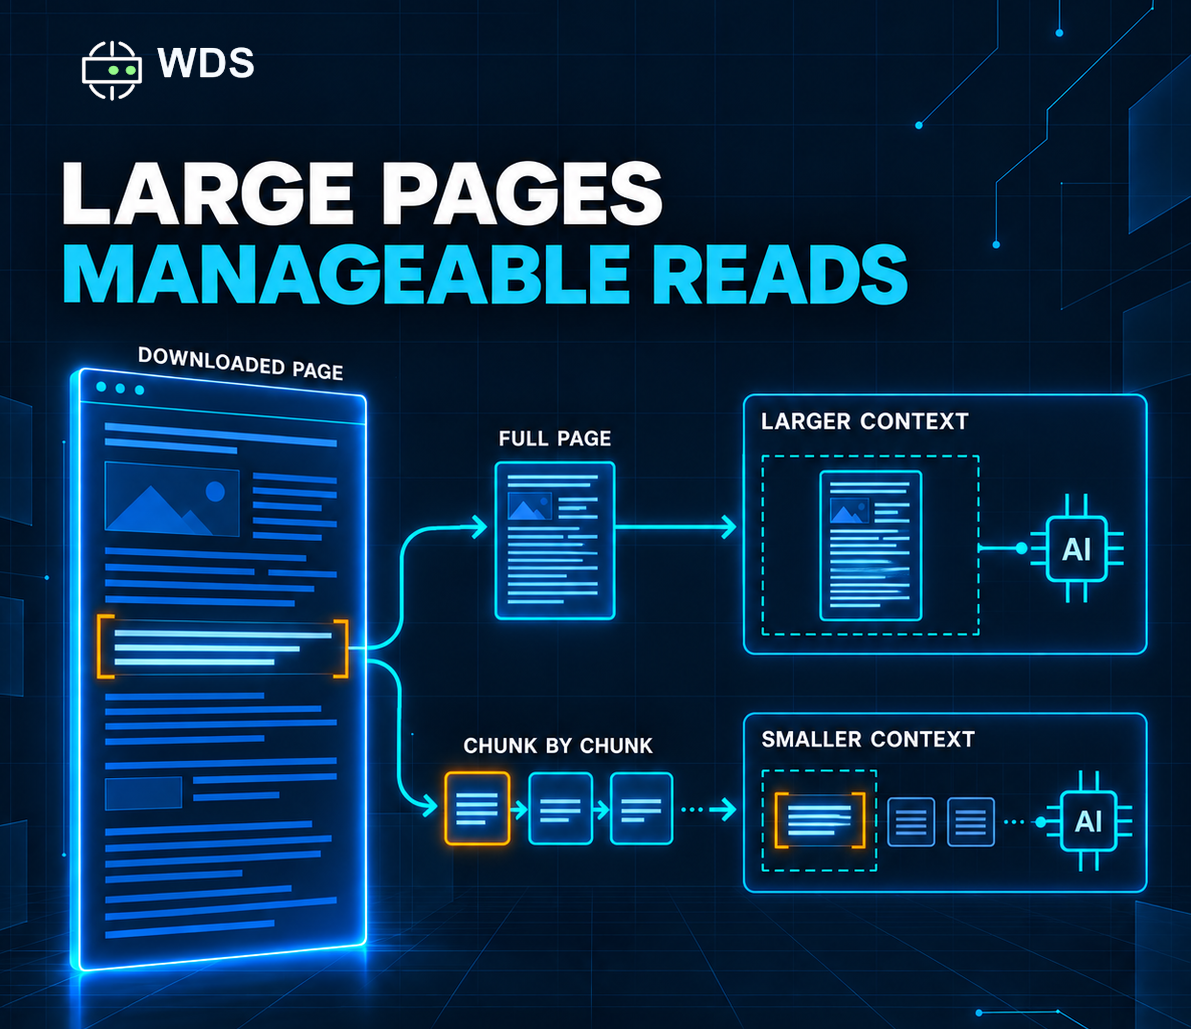
Web Data Source (WDS) gives agents a way to read progressively through its MCP tools:
- WdsFetchChunked starts or resumes downloading a page and returns its task ID.
- WdsGetChunk reads a portion of that downloaded content, with a chosen starting position and maximum character count.
- The response reports the full content length, helping the agent plan subsequent reads.
For an agent reviewing a long technical document, the workflow becomes:
Read a portion → Process it → Retain useful findings → Continue.
By choosing suitable portion sizes and summarizing findings between reads, an agent can work through the page while managing its available context. This helps reduce the risk of oversized inputs across models with different limits.
WDS controls each read in characters; the agent manages the model’s token budget and accumulated context.
Large pages. Manageable reads. More flexibility across AI models.
Explore the corresponding [WDS MCP tools](https://webdatasource.com/releases/latest/mcp/tools/get-chunk.html)
# Give Your Web Data Pipeline a Schedule.
Product catalogs change. Internal documentation evolves. A useful collection workflow needs to run repeatedly.
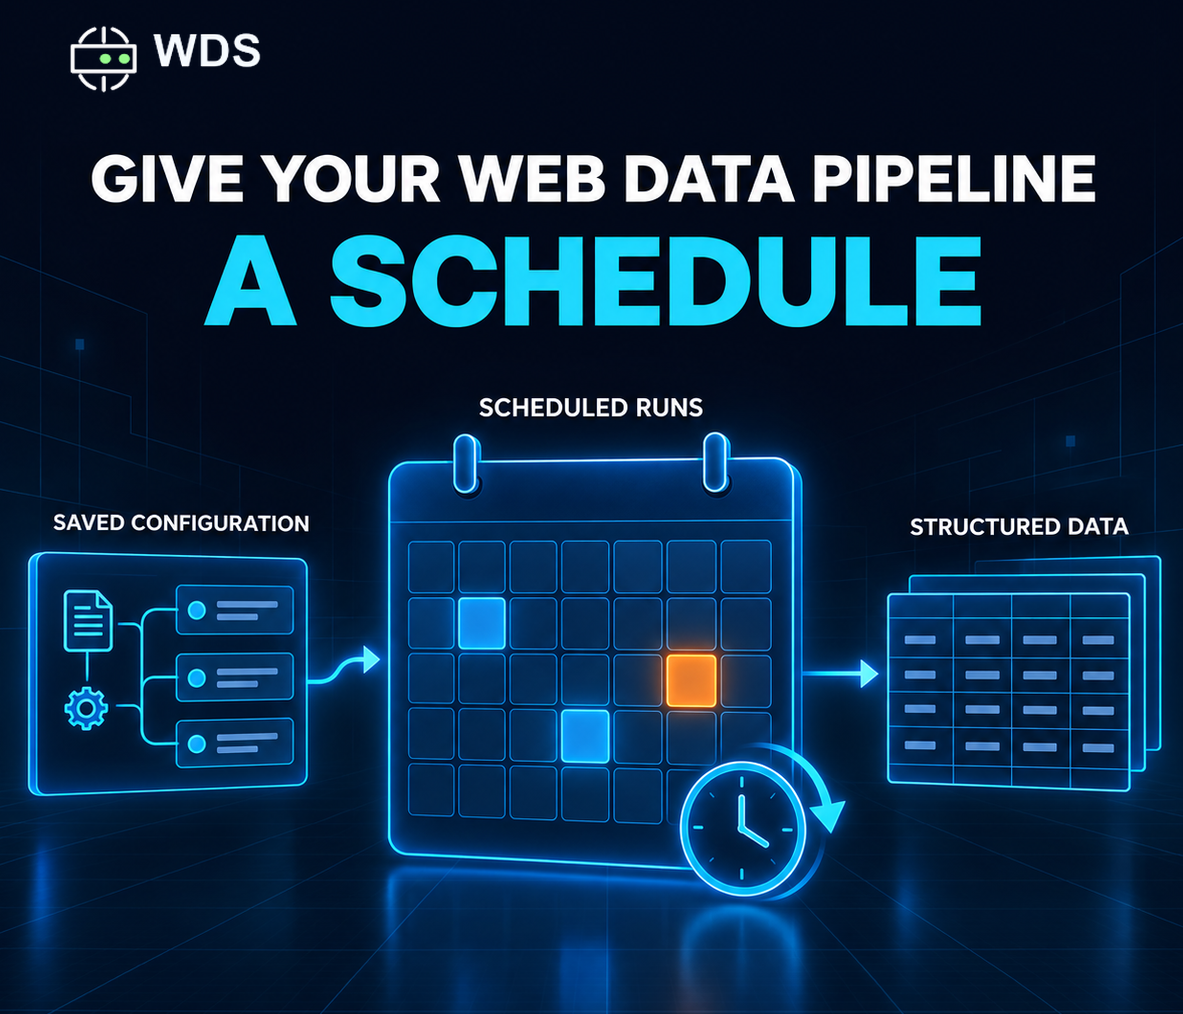
With Traversal Scheduling in Web Data Source (WDS), you can turn a saved crawling and extraction configuration into a recurring collection:
- Define which pages to follow and which fields to extract.
- Set a schedule for automatic Traversal runs.
- Retrieve each run’s structured results for downstream reporting or automation.
For a supplier catalog, that could mean collecting product names, prices, and descriptions on a regular schedule - then making those records available to your procurement analysis workflow.
You retain control: disable scheduled starts when needed and keep manual runs available.
Scheduling is available starting with the Business plan and requires a multi-service deployment.
Explore [WDS Traversal Scheduling](../releases/latest/server/api/traversal-scheduling.html)
# Better RAG Search Starts with Better Chunks
Better RAG search starts with better chunks.
How web content is prepared shapes what your retrieval system can find—and the context it can return.
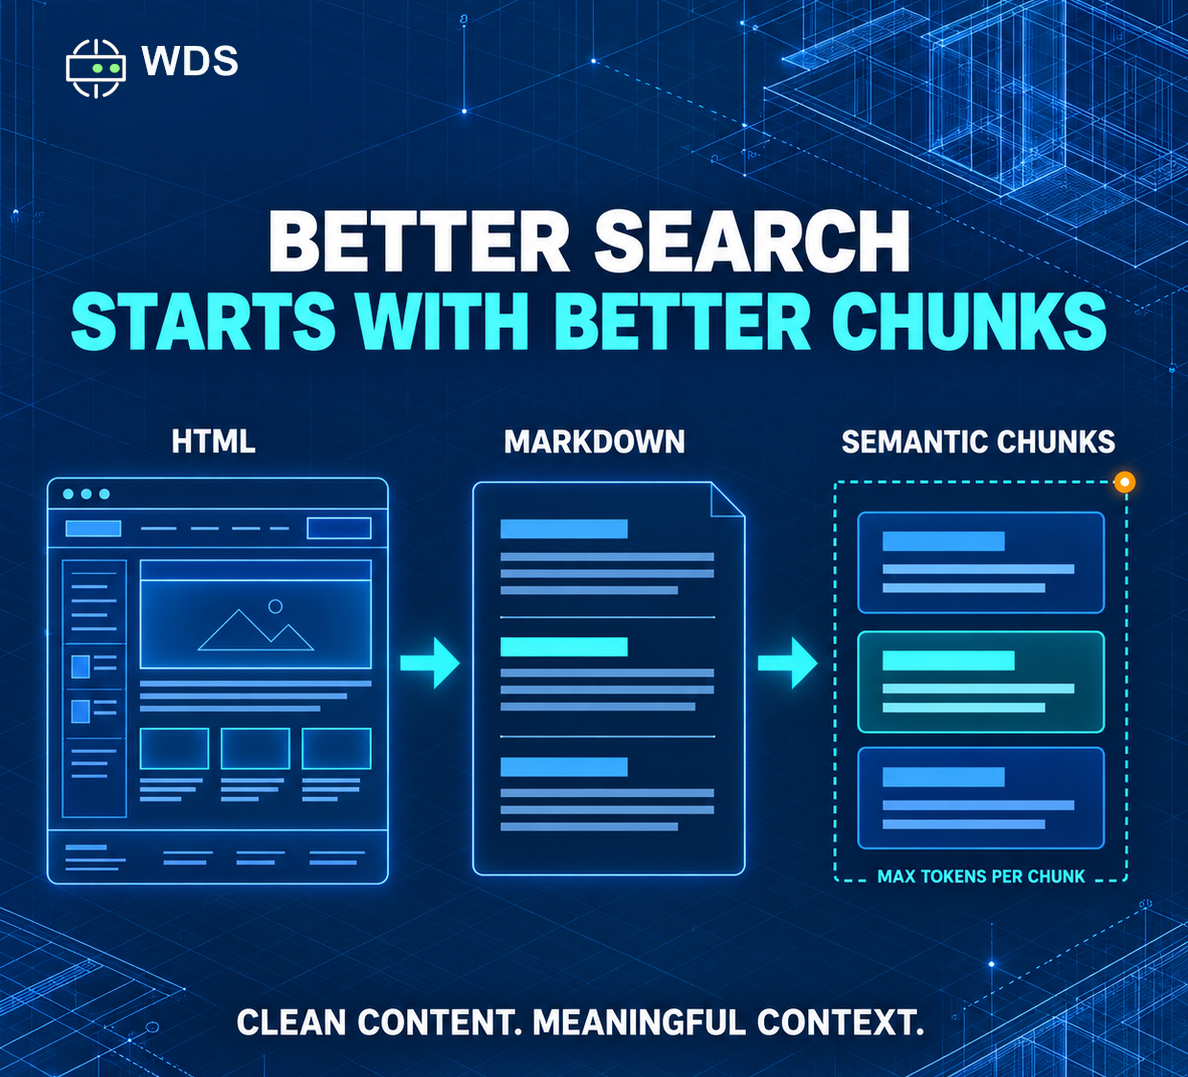
Web Data Source (WDS) prepares that content in two stages:
1. HTML → Markdown
WDS converts page content into Markdown, removing presentation markup and reducing layout noise before indexing.
2. Markdown → Semantic chunks
WDS groups related content into meaningful chunks while respecting the configured maximum tokens per indexed chunk.
The goal is to preserve useful context within a controlled size, helping retrieval return passages that make sense when read on their own.
With MaxTokensPerChunk, you control that size limit. The default is 512 tokens per indexed chunk.
For documentation, policies, and product information, this approach helps prepare cleaner, more coherent context for search and downstream AI answers.
Clean the content. Preserve the meaning. Keep the size under control.
Explore [WDS Retrieval configuration](../releases/latest/server/api/jobs.html#retrievalconfig)
# Link Answers to Their Sources
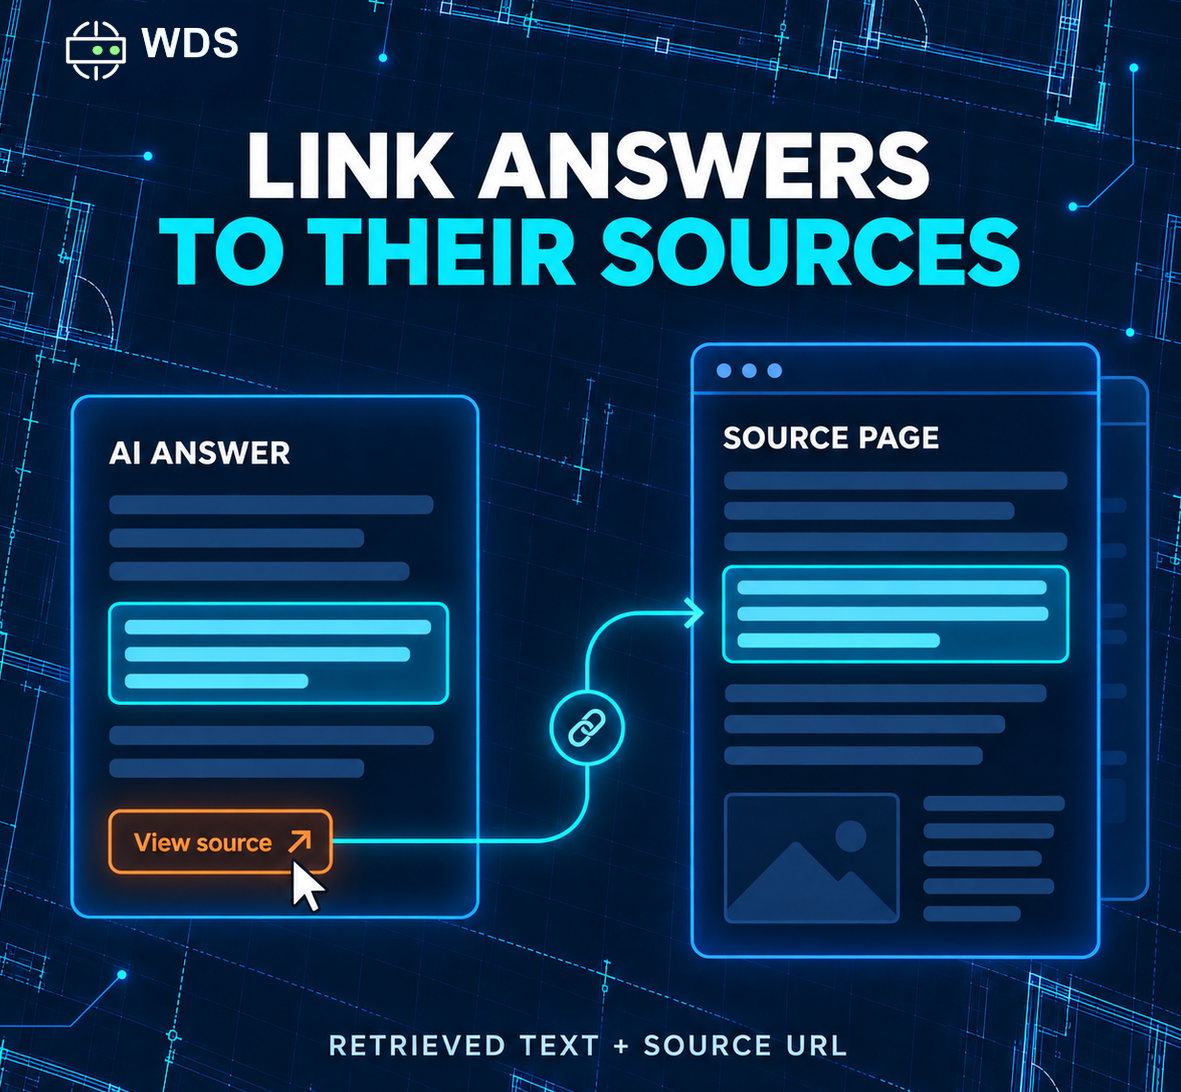
Don’t make users search for the source behind an AI answer. When an assistant summarizes a policy, explains a product requirement, or answers a technical question, the reader should be able to open the supporting page.
Web Data Source (WDS) returns matched text together with the URLs of the source pages containing it.
That gives your RAG application the information to connect an answer to its supporting evidence:
- Show the relevant passage.
- Link directly to the source page.
- Let the reader explore the surrounding context.
For an internal knowledge assistant, that could mean linking a policy answer to the original policy. For a technical assistant, it could mean pointing users to the documentation behind a recommendation.
Make verification part of the experience.
An answer is more useful when the next click takes you to its source.
Explore the [WDS Retrieval API](../releases/latest/server/api/retrieval.html#retrievalitem)
# Evaluate WDS faster—with an All-in-one images!
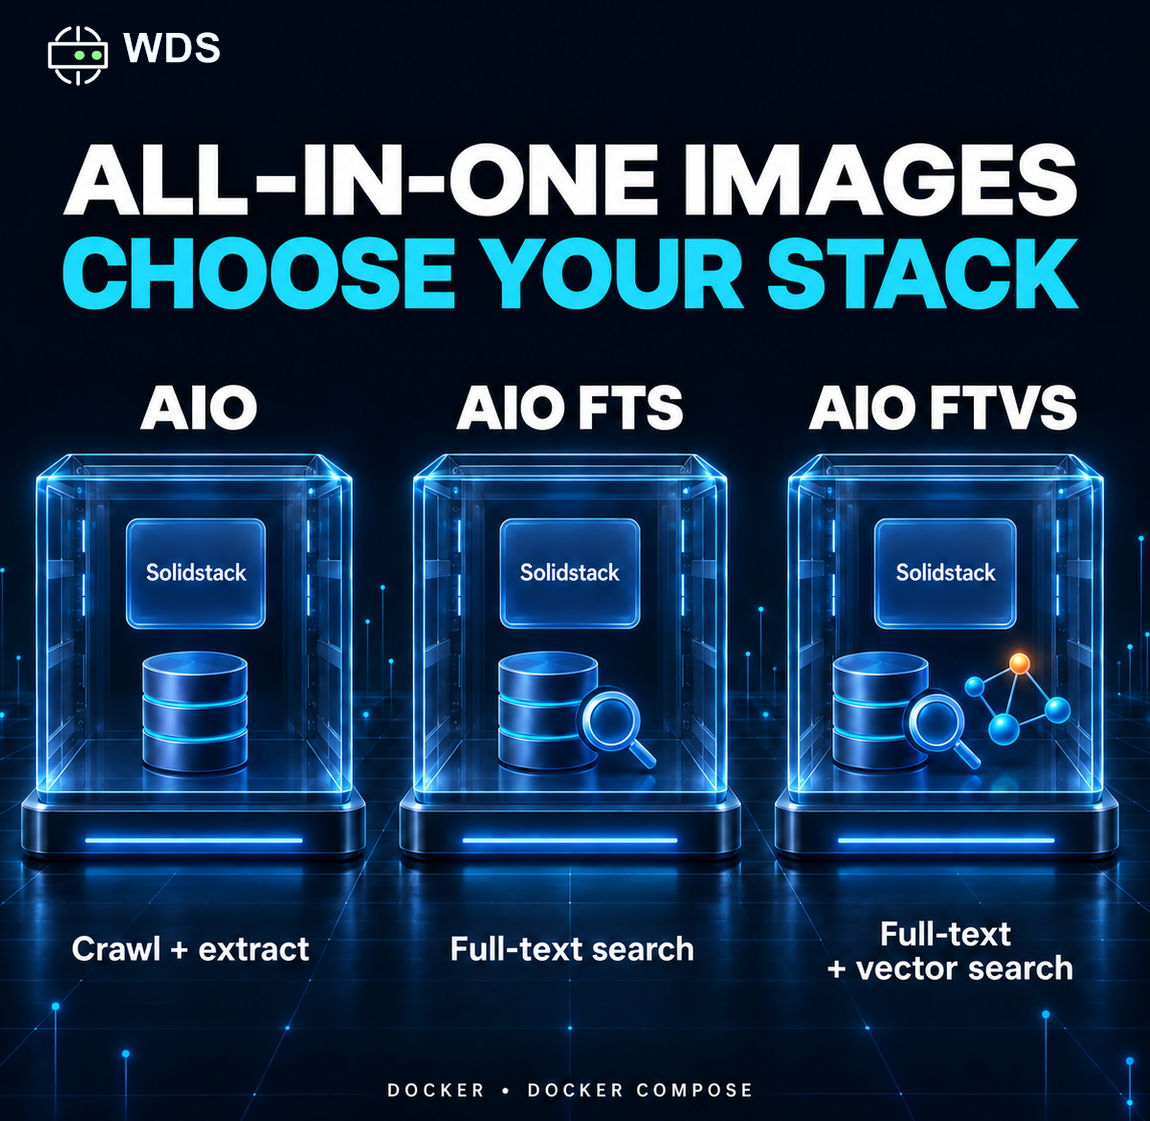
A proof of concept should help you test WDS on your data quickly. Solidstack All-in-one images reduce setup by packaging the application and its supporting services in a single container.
Choose the variant that matches what you want to evaluate:
- AIO - WDS + MongoDB for crawling and structured extraction when Retrieval is not required.
- AIO FTS - WDS + MongoDB Atlas Local, with full-text retrieval enabled by default.
- AIO FTVS - adds Ollama and the preloaded embeddinggemma model, with full-text and vector search configured by default.
Want to evaluate retrieval over internal documentation? FTVS bundles the WDS application, search database, and embedding service together—so you can focus on testing your workflow.
Deploy with Docker or Docker Compose, configure your web resource, and start exploring through the API, Swagger, or MCP.
These images are a practical starting point for fast evaluation and small workloads. When you need independent scaling, fault isolation, or Scheduling, use the multi-service deployment. Less setup. Faster evaluation. More time to test what matters.
Explore the [All-in-one solidstack image variants](../releases/latest/server/services/solidstack.html#all-in-one-image-variants).
# FIPS Images for Web Data Infrastructure in Closed, Regulated Environments
Web data infrastructure for closed, regulated environments (including air-gapped networks).
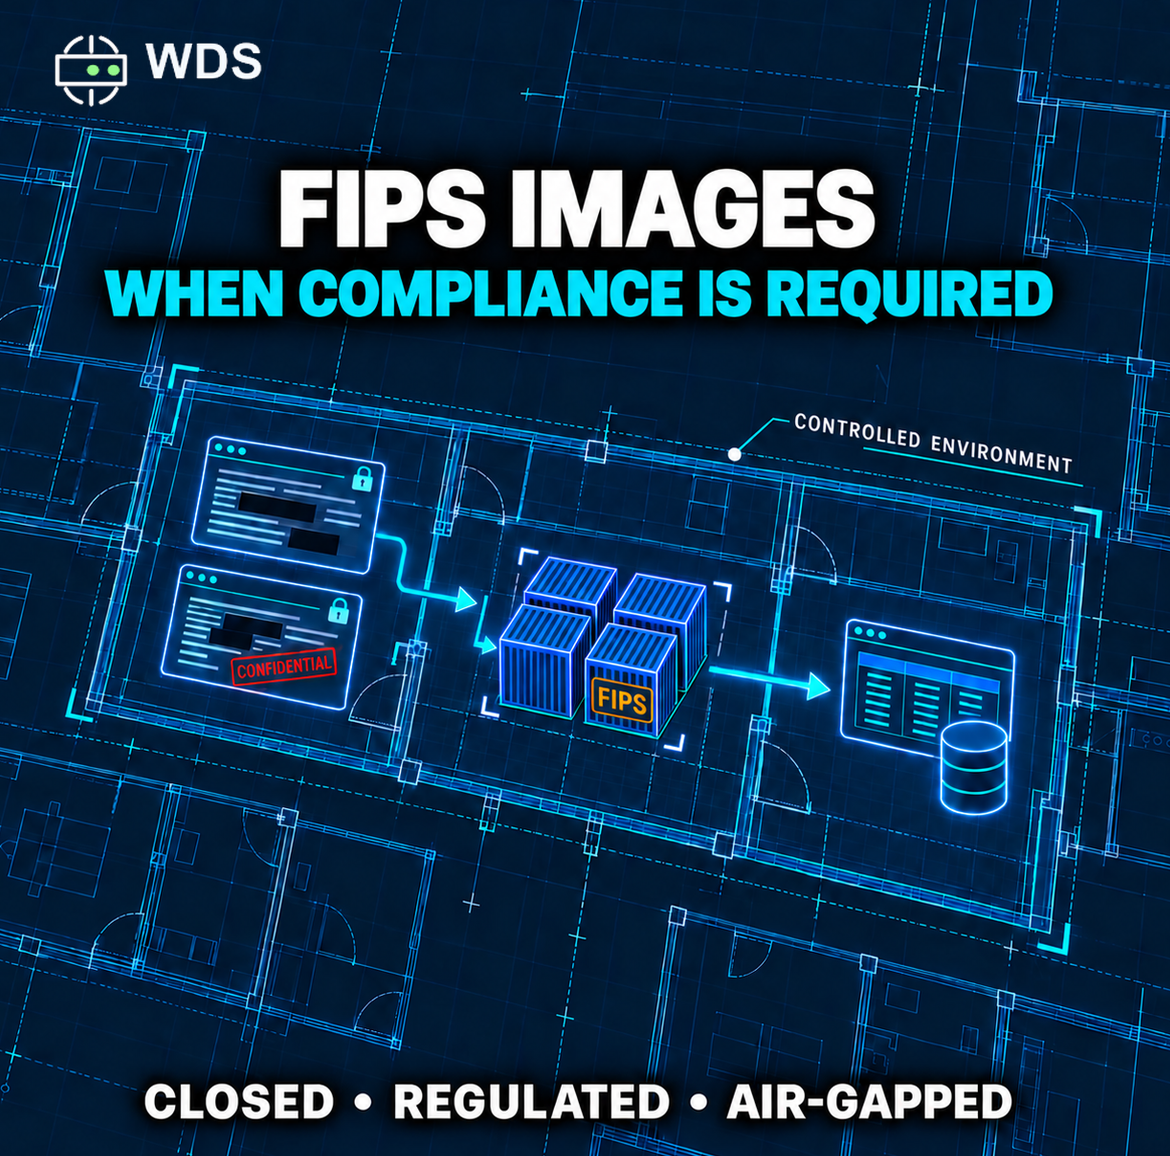
Starting with version 3.0, every WDS service has a FIPS container image variant, including Solidstack - the single-container WDS server. This gives teams additional deployment options for environments with strict cryptographic requirements.
Run web crawling, structured extraction, indexing, and retrieval for RAG inside infrastructure you control, even when that infrastructure is disconnected from the public internet.
WDS already supports air-gapped deployment through scripts that package and transfer container images into private registries. FIPS image availability extends the deployment choices for teams operating in these controlled environments.
Explore the image options in the [WDS v3.0 service documentation](../releases/latest/server/services/index.html#fips-images).
# Store Only What Changed
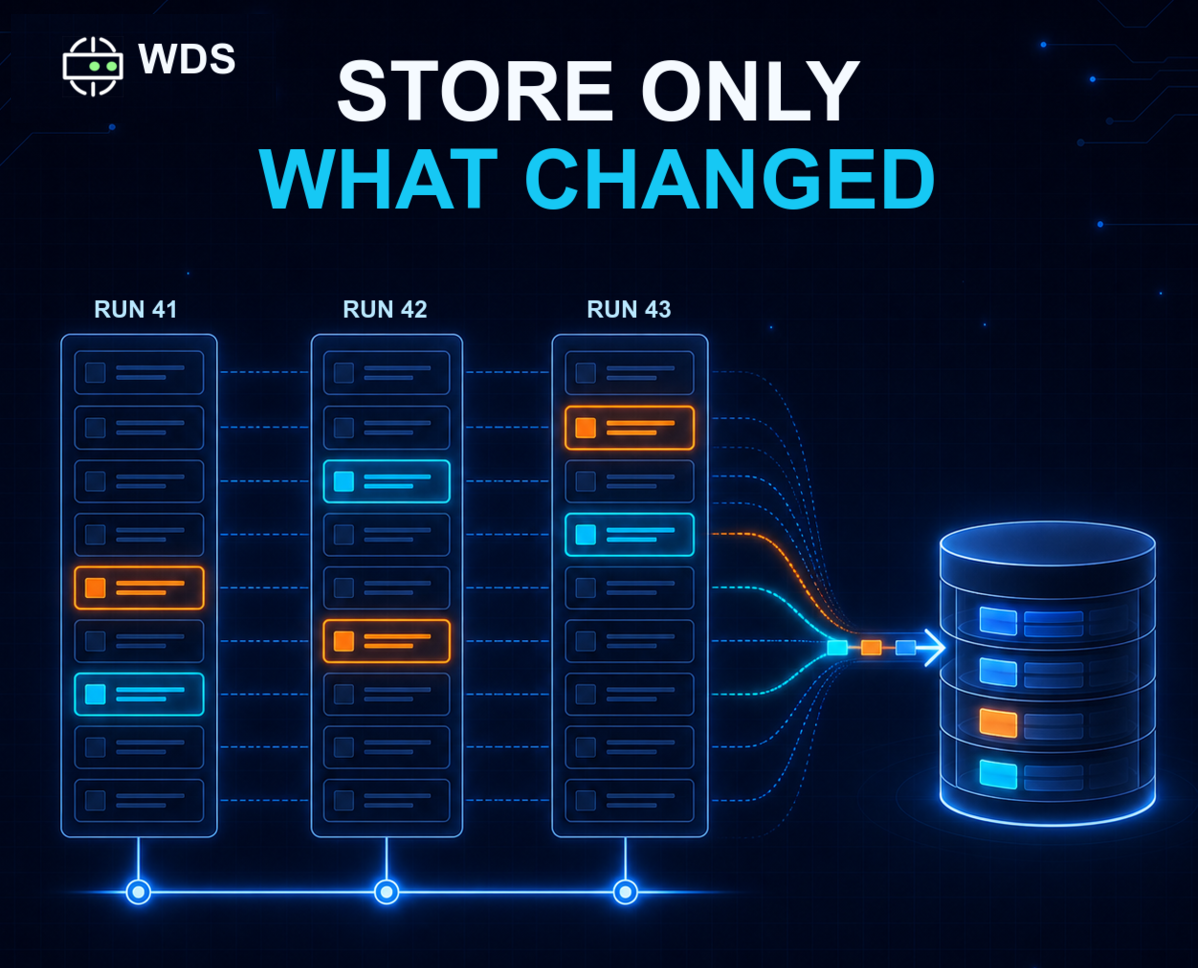
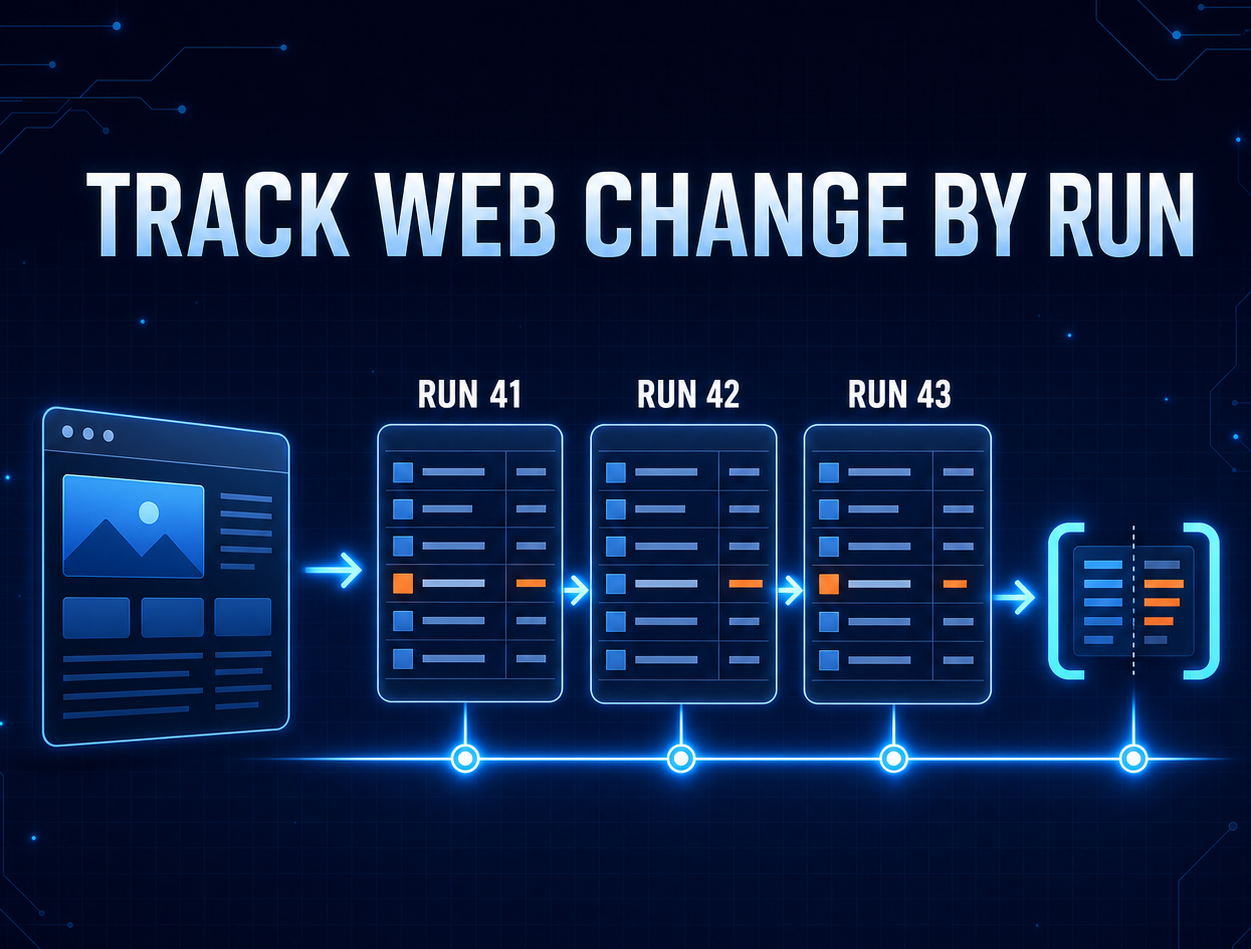
A new Traversal run does not need a new full copy of the data. WDS keeps the recurring collection lean.
Run 41 → Baseline stored
Run 42 → Only price changes added
Run 43 → Only new or updated records added
Unchanged scraped output is not stored again. That limits duplication in the WDS database while preserving a run-by-run history.
With [Get Traversal Run Data](../releases/latest/server/api/traversal.html#get-traversal-run-data), your pipeline can still retrieve any run by number in cursor-paginated batches and work with the complete data for that run.
Complete snapshots when you read. Incremental storage underneath.
Track changes over time—without storing the same values over and over.
# Web Resources Change. Your Data Should Show How.
WDS stores the scraped output from each Traversal run. With [Get Traversal Run Data](../releases/latest/server/api/traversal.html#get-traversal-run-data), you can retrieve any run by its run number in cursor-paginated batches.
That turns recurring collection into comparable snapshots:
Run 41 → Original data
Run 42 → Updated prices
Run 43 → New or changed records
Compare runs in your pipeline to monitor catalogs, policies, documentation, or internal web resources.
One Traversal captures the current state.
Multiple runs reveal change over time.
# Websites Are Graphs. WDS Traversal Turns Them into Trees
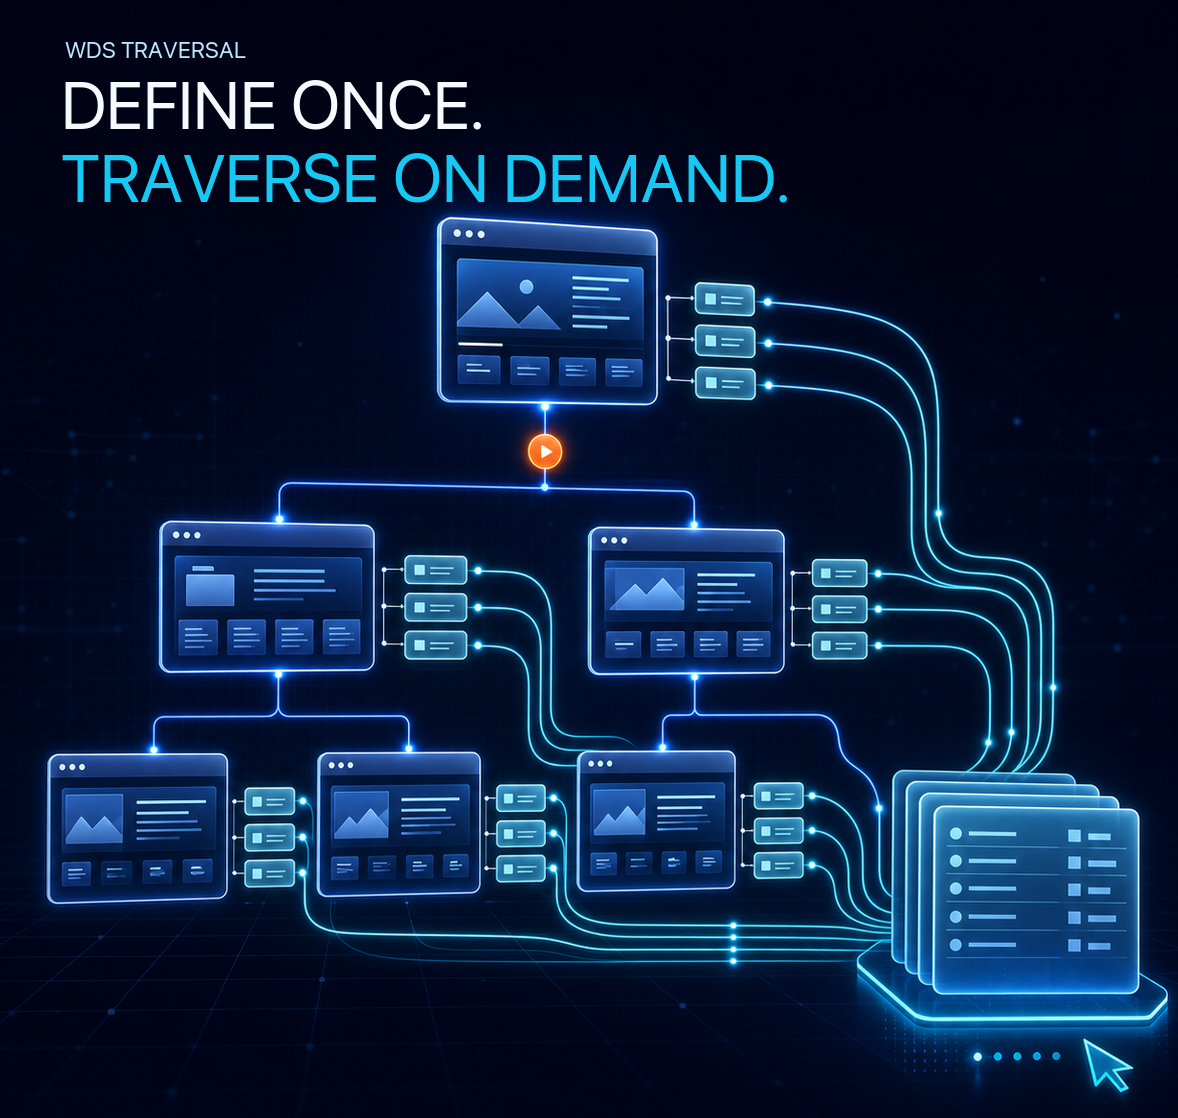
Websites are graphs. WDS Traversal turns that graph into a tree-shaped plan—with no configuration loops by design.
Categories lead to products, products link back to categories, and navigation menus reconnect every page. That structure works for people, but data collection does not need to follow every cycle.
Starting at the root, WDS expands across each level, gathering more detail as new branches are reached and building structured JSON from the collected information.
Every level can define only its children, not point back to a parent. This prevents developers and AI agents from accidentally creating circular traversal paths.
The same tree also controls the output. Stop at a selected level for a concise overview, or continue to the leaves when deeper analysis requires every available detail.
All collected data remains available in the database, while each request returns the depth and detail the user needs. Explore [WDS Traversal](../releases/latest/server/api/traversal.html).
# WDS v3.0 is here
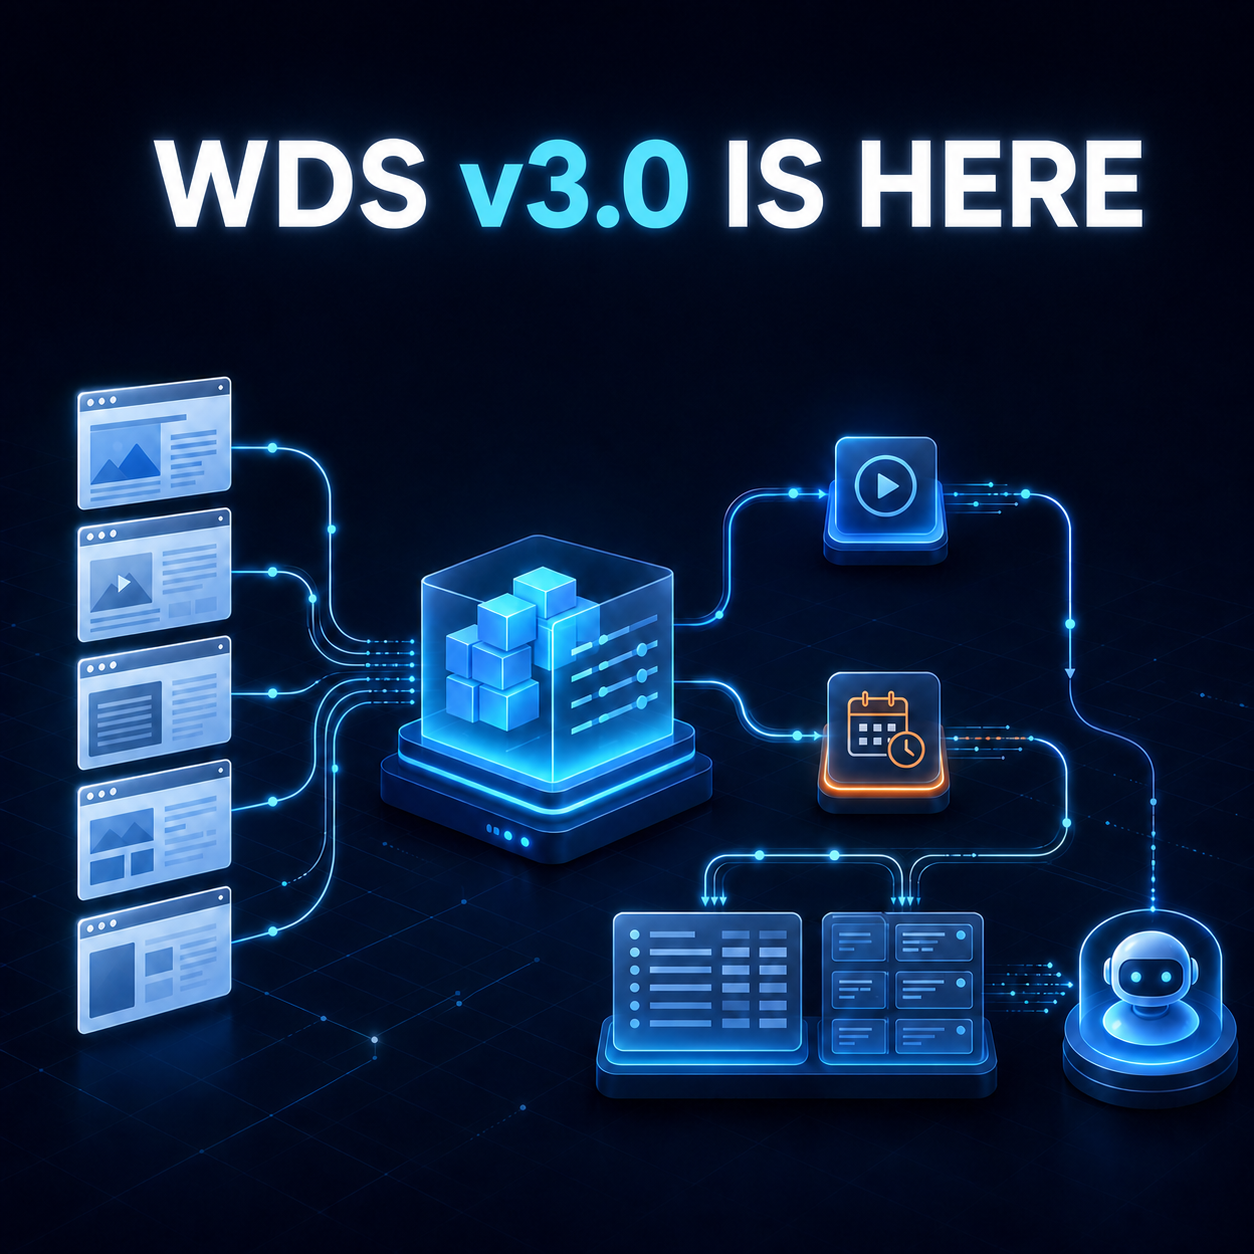
WDS v3.0 turns web crawling into a reusable, trackable data workflow:
- Configure once
- Run on demand
- Schedule recurring collection
- Keep structured web data ready for databases, automations, and AI agents
## What's new
- **Configuration-first workflows** across REST and MCP
- **Traversal Runs** with status, errors, and cursor-paginated results
- **Scheduled Traversal** for recurring data collection
- **Predictable, chunked page retrieval** for AI agents
Explore the release: [WDS v3.0 documentation](../releases/v3.0/index.html)
# Documentation that AI can evaluate
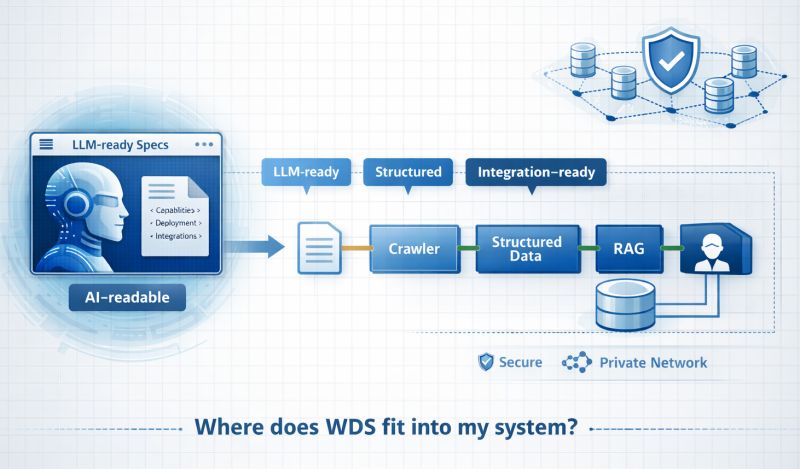
Web Data Source (WDS) provides LLM-friendly documentation that allows AI to determine how WDS fits your architecture automatically.
Simply provide your requirements together with:
- [llms-full.txt - full LLM-readable product specification](../llms-full.txt)
- [posts/full.txt - structured capability and use-case coverage](/posts/full.txt)
Ask AI: "Where does WDS fit into my system?"
AI can identify integration points, supported workflows, and out-of-the-box coverage, including RAG pipelines and structured retrieval scenarios.
Built for environments requiring:
- Air-gapped compatible deployment
- Secure data extraction
- Private network crawling
- Zero-Trust architecture alignment
- Data sovereignty compliance
- Controlled access environments
# Run WDS in minutes - and start using all features for free!
Getting started with Web Data Source (WDS) doesn't require complex setup or long POCs. With the Docker deployment option, the entire platform can be launched locally and fully operational in just a few steps.
Deployment guide: [Docker Compose deployment](../releases/latest/server/deployments/dockercompose.html)
WDS runs as a containerized service, allowing you to start exploring structured web data workflows immediately, including crawling, extraction, and AI-ready pipelines.
Why teams start with Docker
* Quick start with minimal dependencies
* Full platform available from day one
* Works both online and in isolated environments
* Easy transition from local testing to enterprise deployment
* Consistent runtime across development and production
Ready for secure environments from the first run
WDS supports deployment models aligned with modern infrastructure and compliance requirements:
* Air-gapped compatible
* Isolated environment deployment
* Secure data extraction
* No internet dependency when required
* Private network crawling
* Data sovereignty compliance
* Controlled access environments
Start locally, scale to production, or deploy inside a private infrastructure. The same platform supports all scenarios.
WDS transforms web resources into structured, query-ready datasets that power analytics, automation, and AI agents without complex integration work.
# Query Indexed Resources with AI Agents - RAG Workflow from Web Data
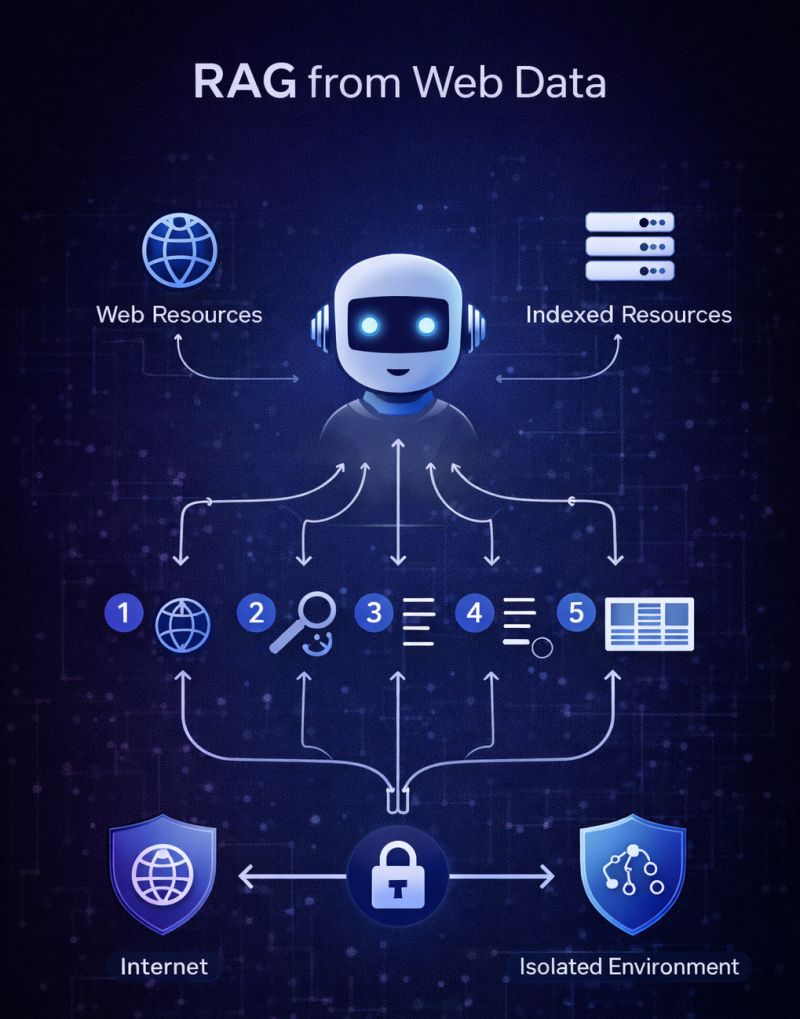
The "Query" MCP prompt in Web Data Source (WDS) demonstrates a RAG (Retrieval-Augmented Generation) workflow applied directly to indexed web resources.
Instead of relying on simple keyword search or opaque retrieval pipelines, the AI agent executes a structured, explainable retrieval process that ensures results are both relevant and verifiable.
Each step forms a transparent reasoning chain, enabling trustworthy AI outputs for automation and decision-making.
The RAG workflow combines semantic understanding with controlled execution logic:
* identify the relevant indexed resource
* build a semantic query based on entities and intent
* retrieve candidate results using defined thresholds
* evaluate relevance of each result step-by-step
* expand the search using related concepts when needed
* perform deep retrieval on the most relevant sources
* generate structured, verifiable output
This transforms web resources into a reliable knowledge layer that AI agents can query with confidence.
Why It Matters
This approach delivers a RAG pipeline where retrieval is transparent, deterministic, and optimized for enterprise usage:
* AI agents query structured knowledge instead of raw HTML
* retrieval logic is explainable and auditable
* semantic expansion improves completeness of results
* deterministic workflows reduce ambiguity
* outputs are reliable for automated decision processes
Works Anywhere Your Data Lives
WDS can operate both on public Internet resources and inside isolated environments, supporting:
* Air-gapped compatible deployments
* Isolated environment deployment scenarios
* Secure data extraction with Zero-Trust architecture principles
* No internet dependency when required
* Private network crawling capabilities
* Data sovereignty compliance and enterprise-grade security
* Controlled access environments for sensitive workloads
Product Perspective
The Query prompt shows how WDS enables enterprise-ready RAG over web data, combining structured retrieval, semantic reasoning, and verifiable outputs to improve accuracy, reproducibility, and governance across AI workflows.
More about this [prompt](../releases/latest/mcp/prompts/query.html)
# "Index" Prompt - Cache the Web, Work Faster
What if your data was already there before your workday even starts?
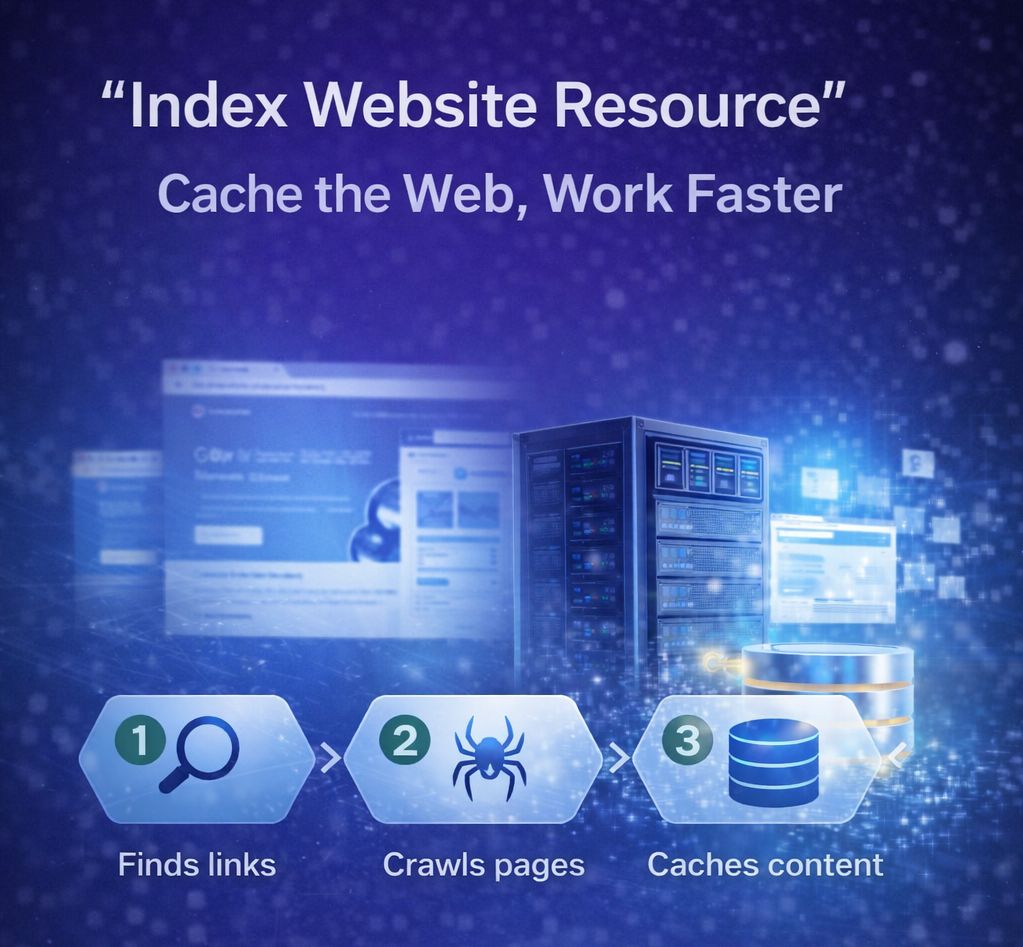
The "Index Website Resource" MCP prompt in Web Data Source (WDS) lets you preload entire websites into cache during off-hours, so your systems can work with data instantly without depending on live websites.
What It Does? It simply:\
1️⃣ Finds all links\
2️⃣ Crawls all pages\
3️⃣ Saves full content to cache
That's it. Everything is preloaded and ready to use.
Why It Matters? During the day:
* No waiting for websites to respond
* No repeated crawling
* No dependency on external resources
Your workflows run on local, stable data.
Where It Gets Even Better
After indexing, you can use the [Retrieve MCP tool](../releases/latest/mcp/tools/retrieve.html) to access cached data efficiently:
* Pull structured content directly from cache
* Extract only what you need
* Work with normalized data instead of raw HTML
* Reuse data across multiple workflows
Where It Helps Most
* SQL workflows - query website data like a database
* RAG pipelines - use cached content for retrieval
* AI agents - operate on fast, predictable data
* Large sites - process everything without network delays
More about this [prompt](../releases/latest/mcp/prompts/index-wr.html)
# "Scrape Data" Prompt
Extracting structured data from websites usually requires complex, fragile scraping scripts. With AI agents and WDS MCP tools, that workflow can be completely different.
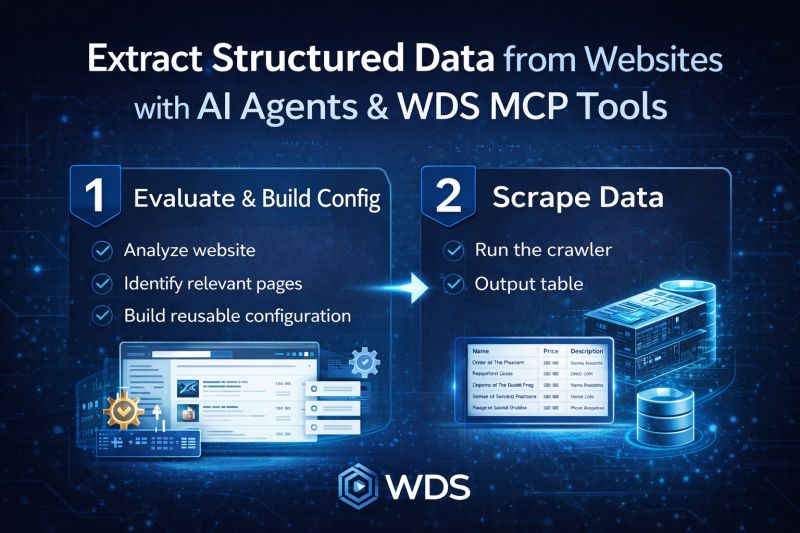
The "Scrape Data" prompt demonstrates how an AI agent can evaluate a web resource and extract only the required data as structured tables.
Instead of blindly crawling pages, the process is split into two clear stages, and every step is executed using WDS MCP tools - no external scripts or custom scraping code required.
1️⃣ Evaluate the resource and build a crawling configuration
First, the AI agent analyzes the website to understand how the data is organized and how to navigate across the resource to collect it completely.
Using WDS MCP tools, the agent:
* inspects the starting page
* evaluates the HTML structure
* determines how to navigate across the website to reach all relevant pages
* identifies which pages contain useful data
* determines which fields are required
* builds a reusable crawling and extraction configuration
This configuration defines how the site should be crawled and what data should be extracted.
The key advantage is that the configuration can be reused as many times as needed.
2️⃣ Scrape data using the configuration
Once the configuration is created, the scraping process becomes simple and repeatable.
Using the same WDS MCP tools, the agent can:
* run the crawler using the existing configuration
* navigate through the site according to the defined rules
* collect only the required fields
* output the results as structured tables, for example: Name, Price, Description
Because the crawling logic is already defined, the same job can be executed periodically to keep datasets up to date.
The same workflow works in enterprise environments where infrastructure and security constraints matter.
More about this [prompt](../releases/latest/mcp/prompts/scrape.html)
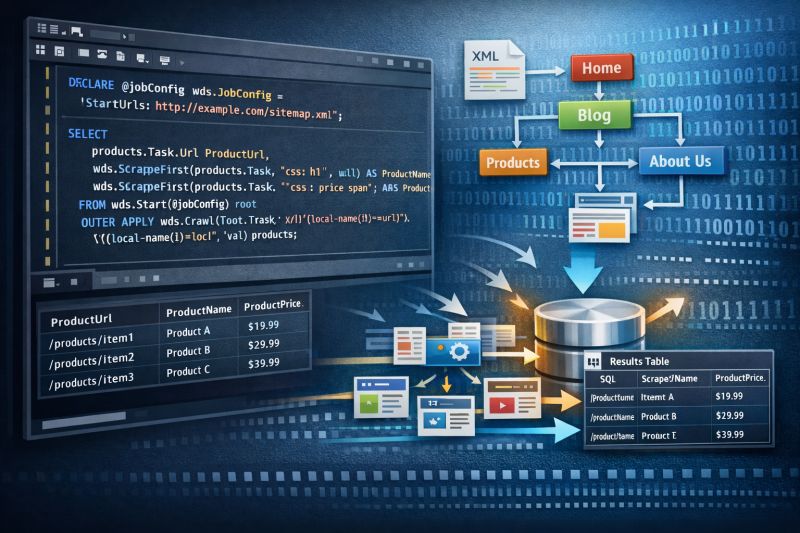
# MS SQL drives structured crawling - starting from a sitemap
In the previous post, we discussed how web data becomes directly usable inside MS SQL queries. Now let us take it one step further.
What if SQL does not just query individual pages, but systematically walks an entire website structure, starting from its sitemap?
The [`Scrape Sitemap` example](../releases/latest/mssql/examples/scrape-sitemap.html) shows how MS SQL, integrated with Web Data Source, can:
* Read and parse an XML sitemap
* Extract page URLs as structured rows
* Crawl and scrape each page
* Normalize the results into relational form
All from inside SQL.
This is not about copying pages. It is about turning a website's declared structure into a queryable dataset.
A sitemap already describes content hierarchy.
SQL simply uses it as an entry point, expanding URLs into rows, scraping fields, and materializing them into tables ready for joins, filters, and analytics.
No external ETL services.\
No scripting pipelines outside SQL.\
No architectural compromises.
Just SQL driving structured web acquisition.
The result?
Websites become declarative data sources.\
Sitemaps become datasets.\
MS SQL evolves from storage engine to structured Internet data ingestion layer.
👉 MS SQL CLR integration (WDS setup): [CLR install guide](../releases/latest/mssql/clr-functions/install.html)\
👉 Video walkthrough - web data directly in MS SQL: [watch here](https://www.youtube.com/watch?v=47U9dXDeT5w)
# “Sliced Resume” Prompt — Phased Website Intelligence
In the previous post, we introduced the “Resume” MCP prompt in Web Data Source — a deterministic workflow that turns a website into a structured company profile.
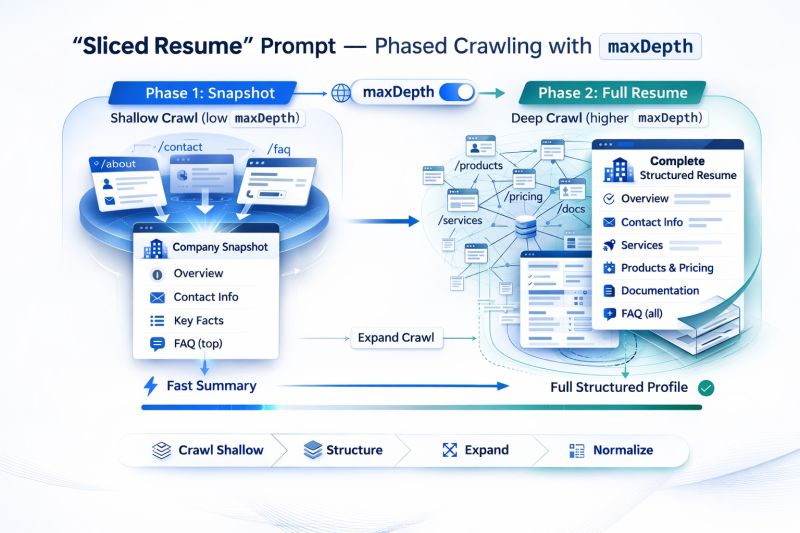
The Sliced Resume enhances it using [`maxDepth`](../releases/latest/mcp/tools/traversal-all.html) to split crawling into phases:
Phase 1 — Fast Snapshot
Shallow crawl of `/about`, `/contact`, `/faq`\
→ Immediate structured summary\
→ Core positioning, contacts, key context
Phase 2 — Full Expansion
Deeper crawl of products, services, pricing, documentation\
→ Complete structured resume
This is not just scraping. It is:
Crawl shallow → Structure → Expand → Normalize
✔ Faster initial insight\
✔ Controlled acquisition\
✔ Incremental intelligence
Website profiling — now progressive and execution-aware.
More: [Sliced Resume](../releases/latest/mcp/prompts/sliced-resume.html)
# “Resume” Prompt
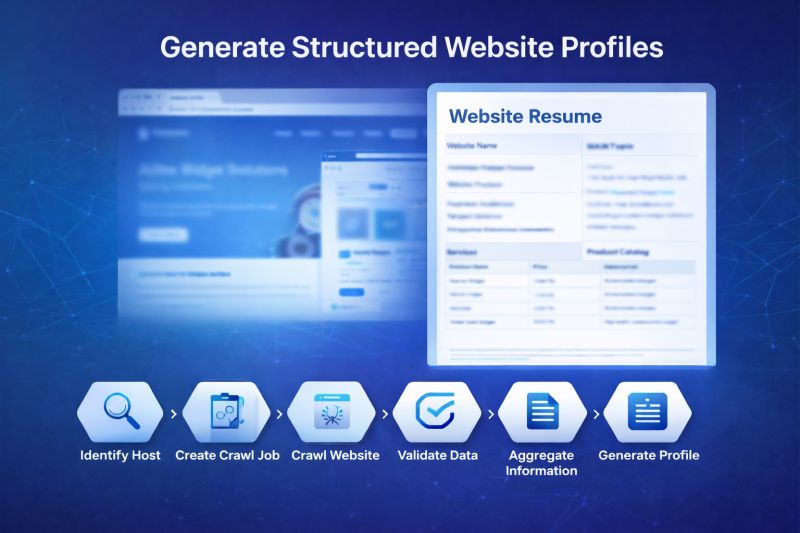
What if any public website could be turned into a structured, machine-ready profile? That’s exactly what the “Resume” MCP prompt in Web Data Source (WDS) does. The execution flow is transparent and deterministic:
1️⃣ Identify host
2️⃣ Create or load crawl job
3️⃣ Crawl the site
4️⃣ Validate completion
5️⃣ Aggregate collected data
6️⃣ Analyze and generate structured output
This isn’t raw scraping.
And not a regular script. The “Resume” prompt is a specialized pseudo-code workflow for AI agents that:
* Calls WDS MCP tools
* Controls execution steps explicitly
* Structures intermediate results
* Applies data comprehension logic on top of collected content
* Produces normalized output objects
It combines tool orchestration and semantic understanding. In other words:\
It’s not “scrape and print.”\
It’s “crawl → reason → structure → present.”
Instead of manually reviewing internet resources, you get standardized company profiles ready for:
* Competitive intelligence
* Market research
* AI pipelines
* Searchable knowledge bases
And importantly — the “Resume” prompt is just a template that generates a structured website profile including:
* Website name
* Main topic
* Contact information
* Target audience
* Services
* Product catalog (structured with pricing)
* FAQ section
It can also be modified to:
* Change the structure of the output
* Focus only on specific sections (e.g., pricing, services, contacts)
* Produce JSON, tables, summaries, or domain-specific formats
* Match exactly the data model required by your customers
Crawl → Collect → Reason → Structure → Present — in the format you define.
More about this [prompt](../releases/latest/mcp/prompts/resume.html)
# Web data, usable directly in SQL
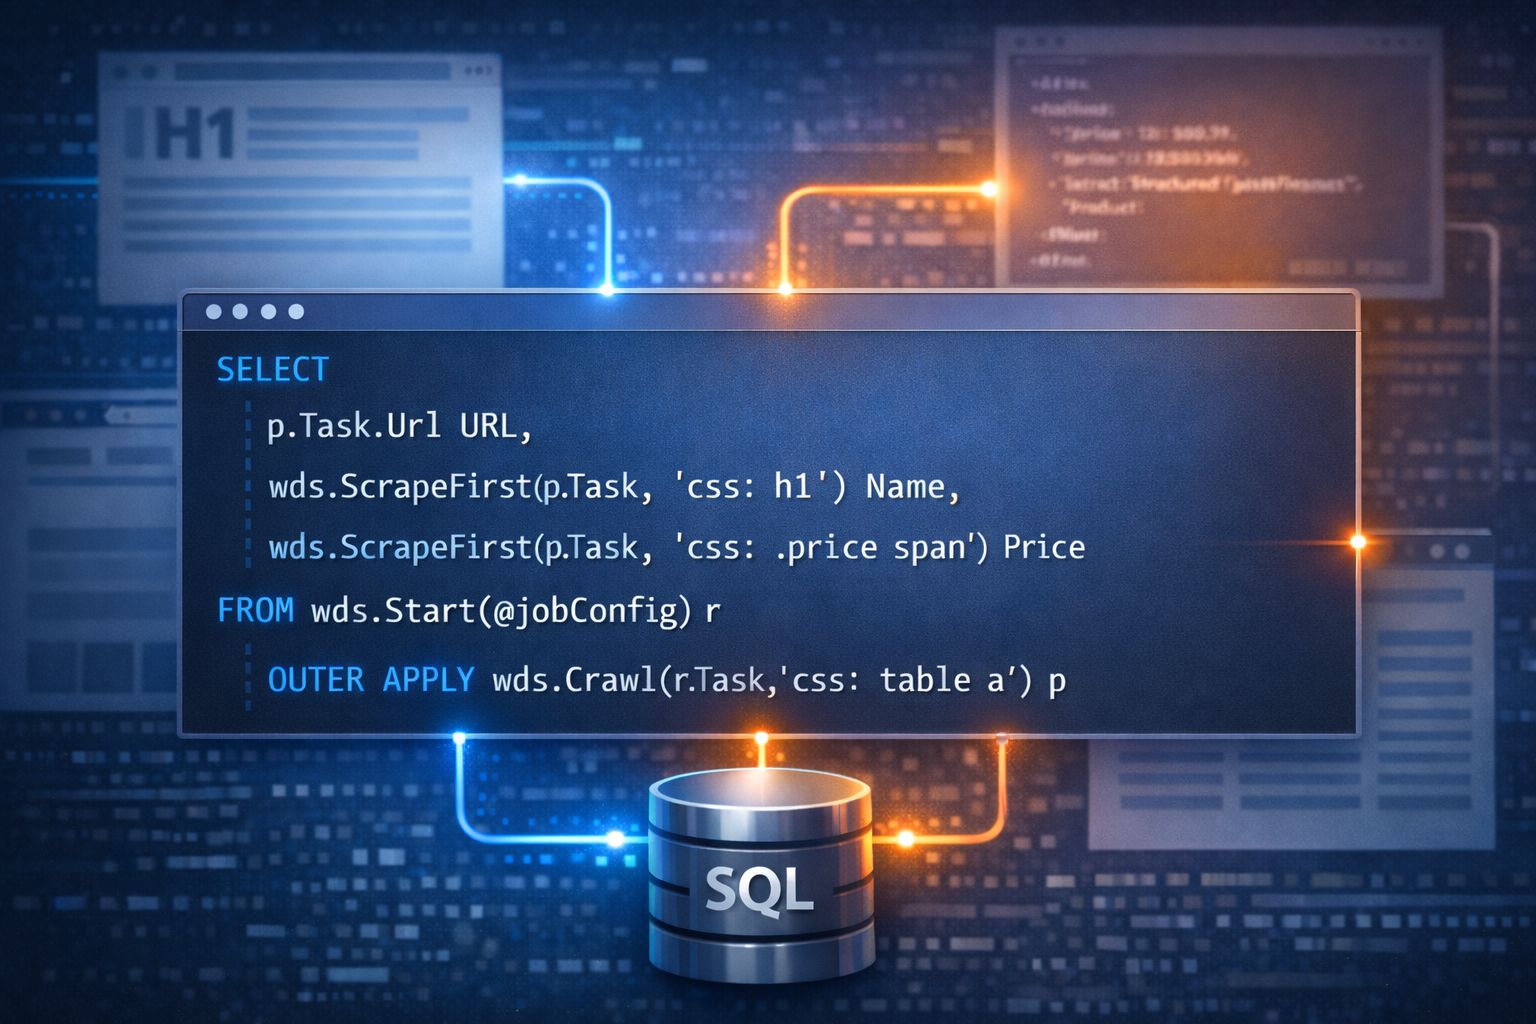
Instead of treating web resources as something external, Web Data Source allows them to be queried and consumed directly from MS SQL — using familiar constructs and the full power of the language.
What matters here isn’t how the data is stored behind the scenes.
Whether a web application is backed by Oracle, PostgreSQL, MongoDB, or something proprietary doesn’t matter at all. Once data is exposed through web pages or APIs, it can be modeled and consumed inside MS SQL queries as structured tables.
This is especially valuable for internal systems:
reporting portals, legacy tools, and internal applications where complex databases are only accessible through the web layer. Without touching the source databases, their data becomes joinable, filterable, and analyzable alongside native SQL tables.
All of this runs where enterprises need it most:
* Private network crawling
* Air-gapped compatible execution with no internet dependency
* Isolated environment deployment aligned with Zero-Trust architecture
* Secure data extraction in a controlled access environment
* Full data sovereignty compliance and enterprise-grade security
The takeaway is simple: if data appears on a web page, it can participate in MS SQL queries — regardless of what database powers it underneath.
📎 Learn more
* How WDS exposes web data as SQL-native functions: [CLR install guide](../releases/latest/mssql/clr-functions/install.html)
* Short video walkthrough → [web data source in action](https://www.youtube.com/watch?v=47U9dXDeT5w)
# MS SQL is no longer just a database
What if your MS SQL environment could pull structured data directly from web resources — using the same operational model it already applies to internal data?
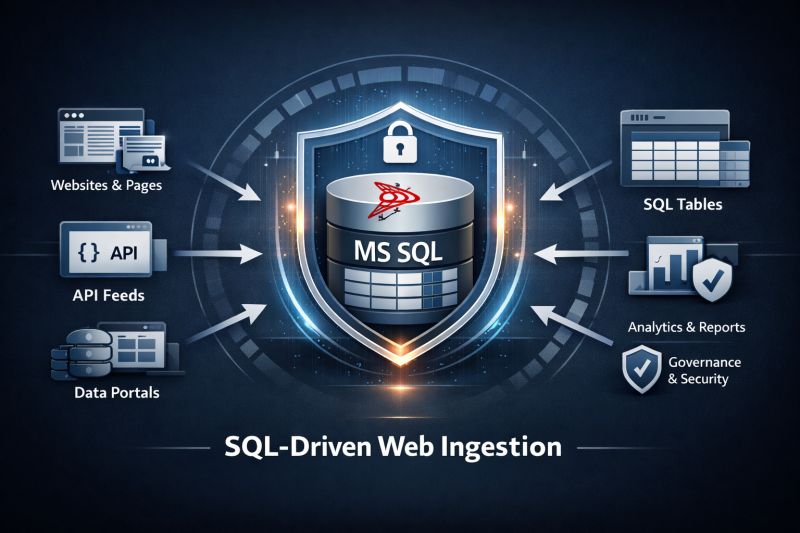
With Web Data Source, MS SQL expands beyond storage and analytics into direct web ingestion, allowing teams to scrape paginated web resources and land the results straight into SQL tables — without introducing external ETL services or breaking enterprise security boundaries.
In this model, MS SQL isn’t just the destination — it becomes the control plane for web data ingestion:
- Scraping jobs are defined and triggered from SQL
Pagination, limits, offsets, and crawl parameters are expressed as SQL-level configuration, not brittle scripts.
- Web pages expand into relational form
Paginated resources are normalized into predictable tables — rows, columns, keys — ready for joins, views, and analytics.
- Incremental collection fits native SQL workflows
Track page numbers, cursors, timestamps, and deltas using standard SQL logic instead of custom glue code.
- No ETL handoff layer
Data flows directly into MS SQL tables — no CSV exports, no message queues, no external schedulers.
- Governance stays inside the database boundary
Permissions, auditing, validation, and lifecycle management use the same SQL controls teams already rely on.
All of this operates inside a controlled access environment with enterprise-grade security, supporting air-gapped compatible, isolated environment deployment, private network crawling, secure data extraction, Zero-Trust architecture, no internet dependency, and full data sovereignty compliance.
👉 [Scraping a paginated web resource directly into MS SQL tables using SQL-driven configuration](../releases/latest/mssql/examples/scrape-paged.html)\
👉 [Video walkthrough](https://www.youtube.com/watch?v=47U9dXDeT5w)
# Infrastructure for trustworthy RAG
Retrieval is not just a feature. It’s infrastructure for trustworthy RAG.
In Web Data Source, Retrieval defines how knowledge is discovered, filtered, and delivered to downstream AI systems — all inside an air-gapped compatible, isolated environment deployment.
Retrieval is the bridge between secure data extraction and accurate AI responses. It ensures your models see the right context, sourced from the right data, under strict Zero-Trust architecture constraints.
What Retrieval enables
- Unified access to full-text search and vector search
- Hybrid retrieval strategies for higher recall and precision
- Predictable, explainable context feeding for RAG pipelines
- Safe operation in private network crawling scenarios
- Full compliance with data sovereignty requirements
- Operation with no internet dependency in a controlled access environment
Designed for enterprise AI. Retrieval in WDS is built to operate where most AI platforms fail:
- Air-gapped environments
- Restricted corporate networks
- Security-first infrastructures
- Regulated industries
It integrates tightly with indexing and enrollment pipelines, ensuring that only approved, curated, and traceable content is ever surfaced to LLMs — preserving enterprise-grade security at every step.
Why it matters for RAG. Better retrieval means:
Less noise in context windows
Fewer hallucinations
More deterministic answers
Stronger trust in AI outputs
If your retrieval layer is weak, your RAG system is unreliable — no matter how powerful the model is.
🔗 Full Retrieval [API reference](../releases/latest/server/api/index.html#retrieval)
# Air-Gapped by Design
Air-Gapped by Design, Not by Compromise
Air-gapped deployment doesn’t have to slow you down.
Web Data Source (WDS) is built for isolated environment deployment, enabling secure data extraction with no internet dependency.
To simplify air-gapped setups, WDS provides ready-to-use scripts that automatically package and deliver all required container images into private container registries — so teams can deploy quickly without custom tooling.
What this enables in practice:
• Air-gapped compatible deployment using mirrored Docker images
• Private network crawling inside internal or classified infrastructures
• Zero-Trust architecture aligned with enterprise security standards
• Data sovereignty compliance by keeping data fully in-house
• Enterprise-grade security within a controlled access environment
WDS treats air-gapped environments as a first-class deployment model — not a special exception.
📘 Learn [more](../releases/latest/server/deployments/airgapped.html)
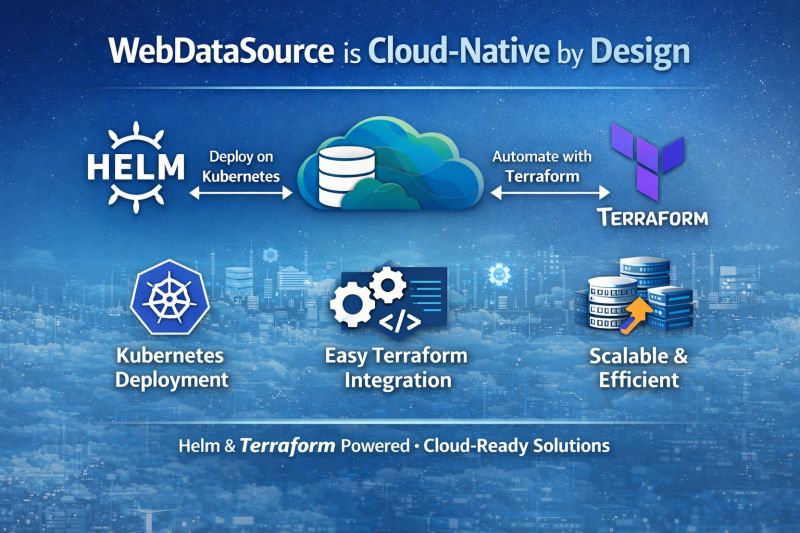
# Cloud-Native by Design
WebDataSource is Cloud-Native by Design
Modern data platforms must run where enterprises operate today — in Kubernetes-based, cloud-native environments.
WebDataSource (WDS) can be deployed into Kubernetes using Helm charts and easily automated with Terraform, making infrastructure provisioning and application deployment part of a single, consistent workflow.
Why this matters:
- Kubernetes-native deployment via Helm
- Seamless Terraform integration for IaC-driven setups
- Repeatable, versioned deployments across environments
- Built for modern, containerized platforms
With Helm + Terraform, WebDataSource fits naturally into cloud-native stacks — from public cloud to private and on-prem Kubernetes clusters.
📘 Learn [more](../releases/latest/server/deployments/helm.html)
# Retrieval Config
Precision-driven Retrieval for RAG — built for secure, controlled environments.
RetrievalConfig in Web Data Source defines exactly what content becomes searchable intelligence inside your air-gapped compatible, isolated environment deployment.
It gives teams full control over what gets embedded, ensuring secure data extraction, data sovereignty compliance, and enterprise-grade security in a Zero-Trust architecture.
Why RetrievalConfig is a game changer\
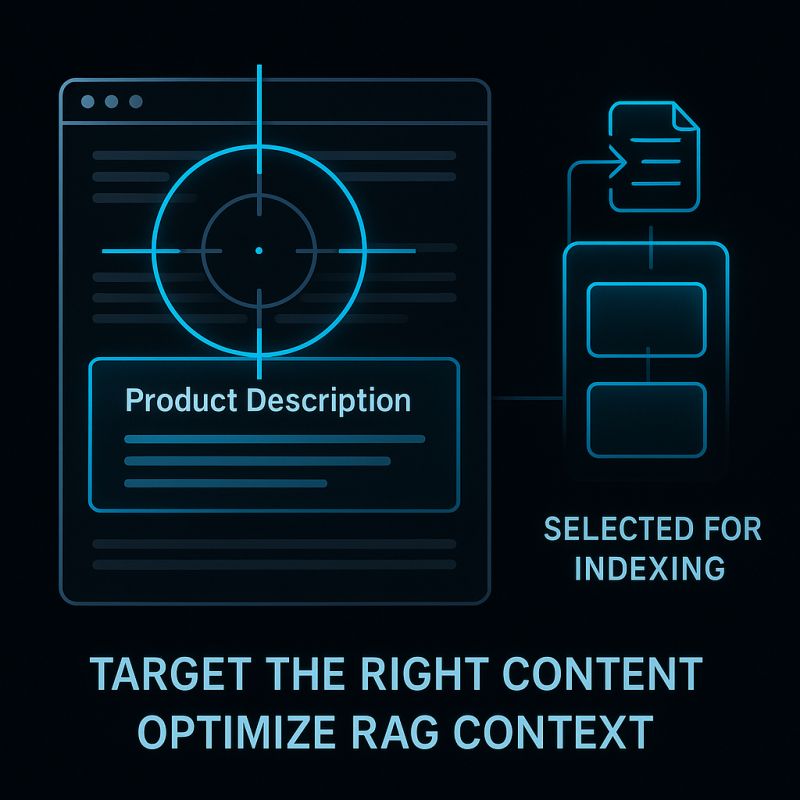
✔️ Selective indexing — enroll only the meaningful parts of a page: product descriptions, documentation bodies, structured details\
✔️ Noise-free retrieval — exclude menus, ads, boilerplates, and footers from embeddings\
✔️ High-quality RAG — better vectors, fewer hallucinations, more relevant answers\
✔️ Works with private network crawling, entirely no internet dependency\
✔️ Guaranteed compliance in controlled access environments
How it works
PathPattern-based targeting - define which URLs or URL segments should be indexed.\
CSS/XPATH selectors - extract just the valuable content blocks for embedding.\
Token-aware chunking - control chunk sizes to match your LLM architecture, ensuring stable, consistent embeddings.
Together, these capabilities let you build a curated, hyper-relevant knowledge base from any website — including those inside private or restricted networks — while preserving maximum security and architectural control.
🔗 Full [API reference](../releases/latest/server/api/jobs.html#retrievalconfig)
# Cross Domain Access
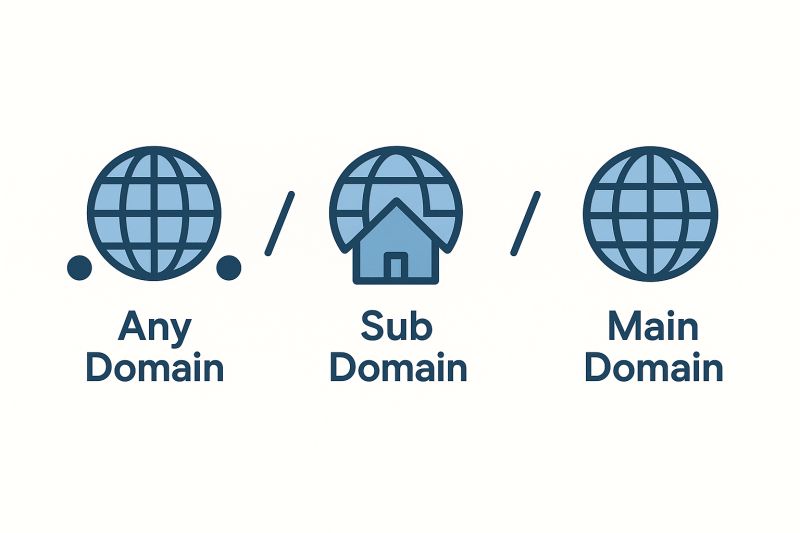
🌐 CrossDomainAccess — Control Exactly Where Your Crawls Are Allowed to Go
When your data pipelines depend on predictable, compliant, and secure crawling behavior, controlling domain boundaries becomes essential.\
CrossDomainAccess in WDS lets you define whether your crawler stays on the main domain, includes subdomains, or can reach out to any external domain — giving you full control over scope and security.
Choose the policy that fits your environment:\
Main Domain — restrict navigation strictly to the primary domain\
Sub Domain — include trusted internal subdomains\
Any Domain — allow full cross-domain exploration when needed
This flexibility is designed for modern, security-driven infrastructures and blends seamlessly with WDS’s core strengths:\
✔ Air-gapped compatible\
✔ Isolated environment deployment\
✔ Secure data extraction\
✔ Zero-Trust architecture\
✔ No internet dependency\
✔ Private network crawling\
✔ Data sovereignty compliance\
✔ Enterprise-grade security\
✔ Controlled access environment
Explore full [documentation](../releases/latest/server/api/jobs.html#crossdomainaccessconfig)
# Crawlers Protection Bypass
🤖 Responsible Crawling with CrawlersProtectionBypass
Some web resources intentionally slow down or limit automated traffic — not to block you, but to protect themselves.
WDS gives you fine-grained tools to cooperate with those systems, avoid overload, and ensure your crawler behaves like a good citizen on the network.
What it does
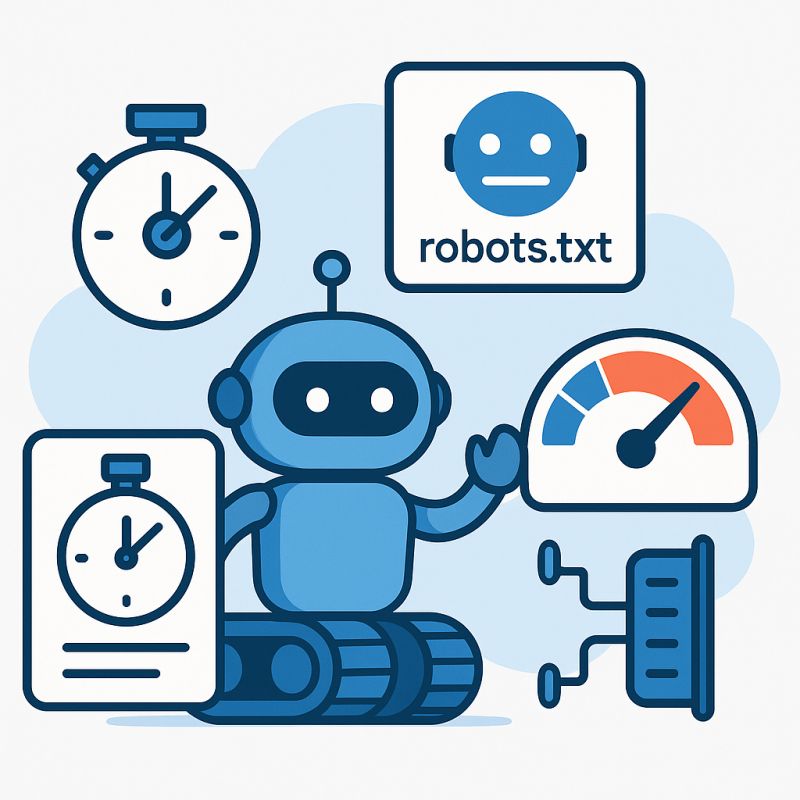
CrawlersProtectionBypass doesn’t “bypass protection” — it helps your crawler adapt:
- MaxResponseSizeKb — Stop oversized downloads before they hurt performance
- MaxRedirectHops — Avoid redirect spirals common on legacy or misconfigured sites
- RequestTimeoutSec — Prevent hanging requests from stalling the crawl
- CrawlDelays — Add per-host pacing to avoid throttling and respect servers’ capacity. robots-guided delays — Let WDS follow robots.txt delay rules automatically
Why it matters
✔️ Prevents your crawler from harming fragile or old intranet systems\
✔️ Reduces the chance of the target throttling or blocking your requests\
✔️ Improves crawl stability on private networks, legacy apps, and low-capacity servers\
✔️ Plays nicely with robots.txt and site owners’ expectations\
✔️ Makes WDS a safe crawler for sensitive enterprise environments
Backed by WDS security & deployment standards
Air-gapped compatible • Isolated environment deployment • Secure data extraction • Zero-Trust architecture • No internet dependency • Private network crawling • Data sovereignty compliance • Enterprise-grade security • Controlled access environment
📘 [Docs](../releases/latest/server/api/jobs.html#crawlersprotectionbypass)
# Download Error Handling
💡 Keep Your Crawls Resilient with DownloadErrorHandling
Network issues shouldn’t stop your data flow.
With DownloadErrorHandling, WDS gives you full control over how the crawler reacts to transient download errors — keeping your pipelines stable and uninterrupted.
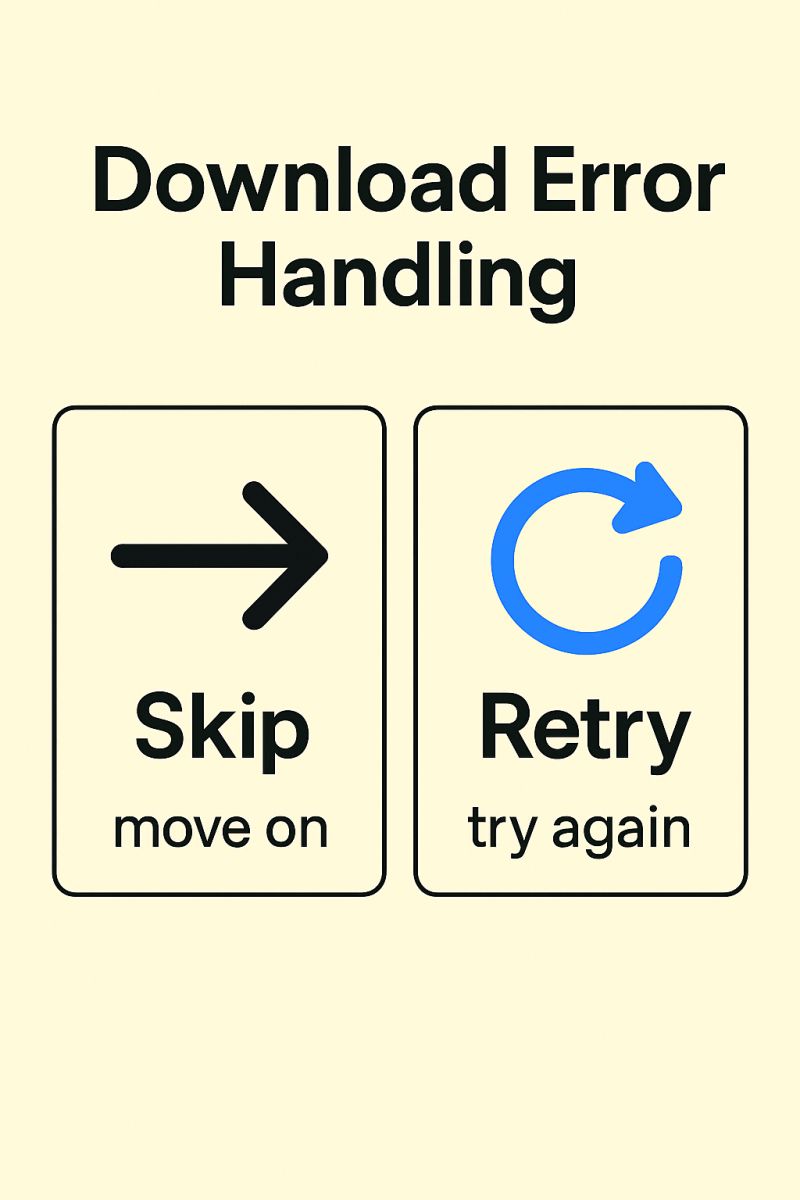
Choose your strategy:\
➡️ Skip — move on and keep crawling\
🔁 Retry — try again with custom delay and retry limits
Because reliable crawling isn’t about avoiding errors — it’s about handling them intelligently.
Reliable crawling • Controlled recovery • Enterprise-grade resilience
Built for:\
🛰️ Air-gapped compatibility\
🔒 Isolated environment deployment\
🧠 Secure data extraction\
🧩 Zero-Trust architecture\
🌐 Private network crawling\
📜 Data sovereignty compliance\
🏢 Enterprise-grade security
See the [documentation](../releases/latest/server/api/jobs.html#downloaderrorhandlingconfig)
# Cookies Config
🍪 CookiesConfig — Bringing Legacy Compatibility to Modern Crawling
Many older or legacy web applications still rely heavily on session cookies to keep users authenticated and preserve navigation states between requests.
With CookiesConfig, WDS crawler speaks their language — ensuring smooth data extraction from systems where cookies remain the backbone of session management.
What it does:
Controls cookie persistence between requests to maintain sessions or state across navigations.
UseCookies: Bool — Save and reuse cookies between requests.
Why it’s valuable:\
✅ Enables crawling of older systems using traditional cookie-based sessions\
✅ Maintains state across navigation in classic intranet and enterprise apps\
✅ Reduces re-authentication overhead\
✅ Increases crawl success rate for legacy web environments
Combined with WDS’s air-gapped compatibility, isolated environment deployment, and Zero-Trust architecture, this feature ensures secure data extraction even from private or legacy systems — while maintaining data sovereignty compliance and enterprise-grade security.
📘 Learn [more](../releases/latest/server/api/jobs.html#cookiesconfig)
# Https Config
🔒 How to Work with Self-Signed Certificates
Sometimes your internal web resources run on self-signed certificates — and that’s perfectly fine.
With HttpsConfig, WDS lets you define HTTPS validation behavior for your crawling jobs.
By enabling SuppressHttpsCertificateValidation: true, you can securely crawl hosts that use non-public or custom certificates without interruptions — ideal for intranet systems, testing environments, or isolated deployments.
See [documentation](../releases/latest/server/api/jobs.html#httpsconfig)
✅ Works seamlessly in air-gapped or private network environments\
✅ Supports Zero-Trust architecture principles\
✅ Enables secure data extraction even from self-signed HTTPS sources\
✅ Perfect for on-prem and enterprise-grade deployments
Whether your infrastructure follows data sovereignty compliance or runs in a controlled access environment, WDS adapts — no internet dependency required.
# Restart Config
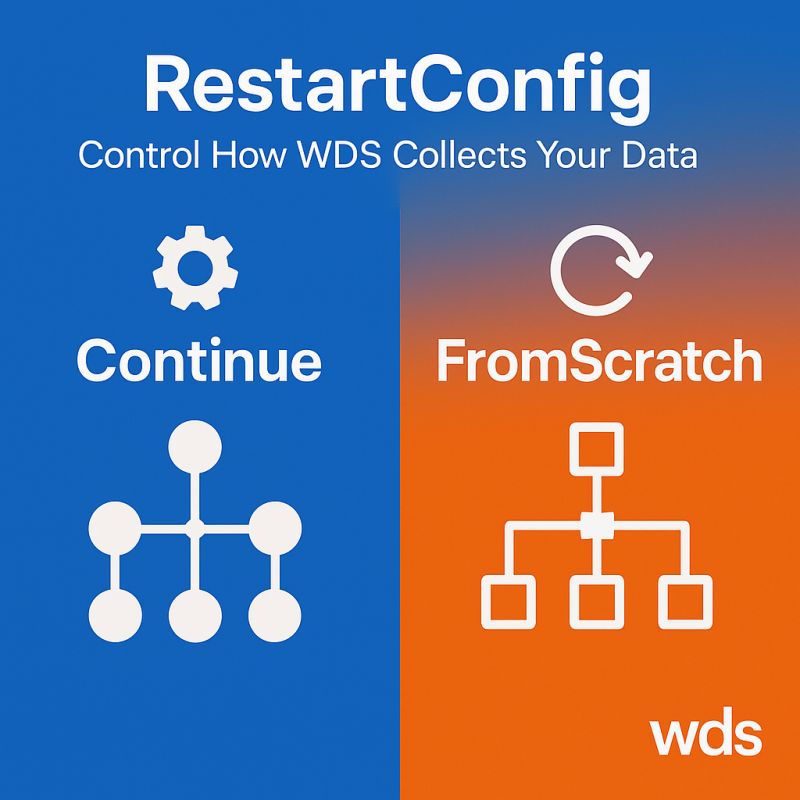
♻️ RestartConfig: Full Control Over Your Data Refresh Strategy
When working with large data sources, you often face a choice —
keep collecting new data or start from scratch.
With RestartConfig in Web Data Source, you can decide exactly how your job restarts:
🔹 Continue — keep the existing cache and resume collection from where you left off. Fast, efficient, and resource-friendly.\
🔹 FromScratch — clear everything and re-index the entire source when major changes or new structures appear.
Take control over your data pipeline — refresh intelligently, restart when needed.
Because precision and flexibility make all the difference.
👉 Learn more in the [docs](../releases/latest/server/api/jobs.html#jobrestartconfig)
# Headers Config
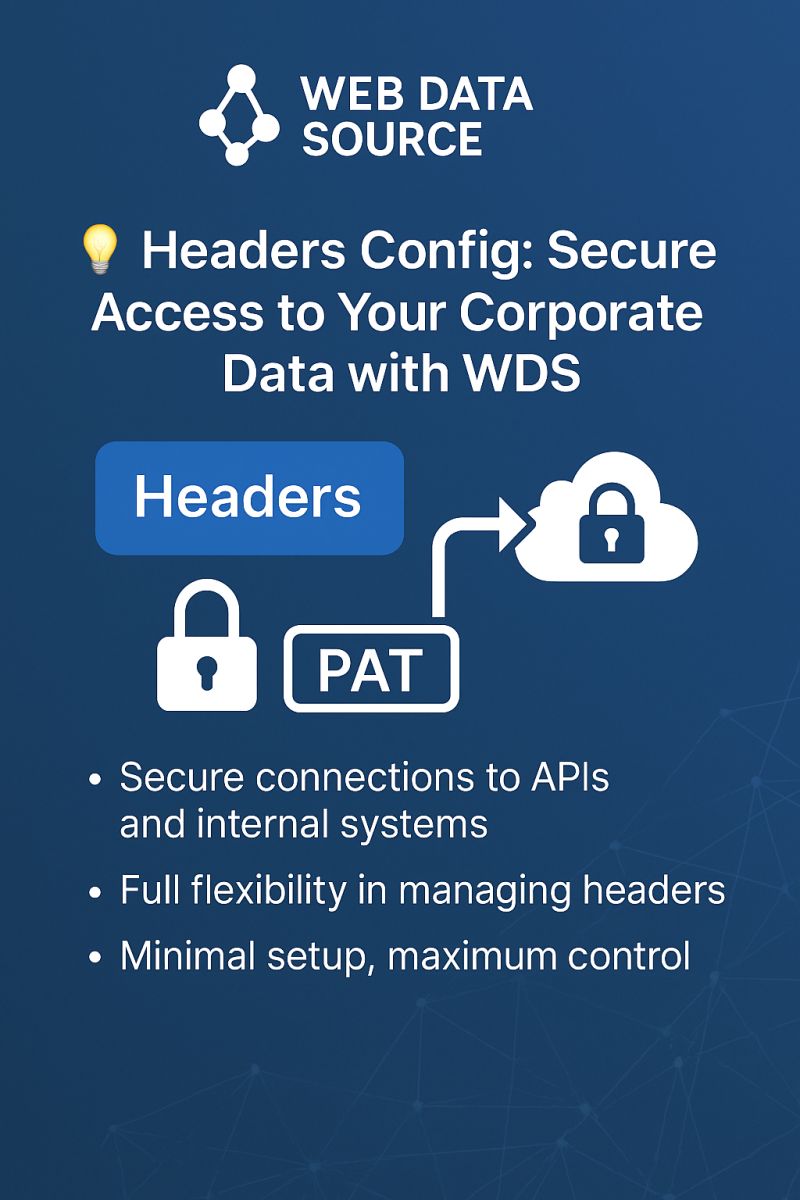
Zero Trust Friendly Access to Your Corporate Data
With Headers Config in Web Data Source (WDS), you can securely connect to APIs and internal systems across Internet and Intranet using custom HTTP headers and Personal Access Tokens (PAT) — all in a Zero Trust–ready way.
🔐 Safe integrations.\
⚙️ Full flexibility.\
⚡ Setup in minutes, not weeks.
Example:
Authorization: "Bearer token"
Expand your data access — without compromising security.
👉 Learn [more](../releases/latest/server/api/jobs.html#headersconfig)
# Proxy Config
Proxy Config in WDS — Full Control and Privacy\
Collect data with confidence:
- Flexibly manage proxy pools for different domains;
- Set smart retry rules to handle failures seamlessly.
Most importantly — 🔒 your privacy.
The source you collect data from will never know who is requesting it and cannot tamper with the information. Your campaigns remain fully protected from manipulation or distortion.
Proxy Config turns proxy management into a powerful tool: you are free to use any proxy types from any providers, without limitations.
Make your data pipeline as resilient and secure as possible — with Web Data Source.
👉 See [documentation](../releases/latest/server/api/jobs.html#proxiesconfig)